Submit a job and collect the result later
An async request returns a job id straight away while the scrape runs in the background. You poll the job for the result, or give an HTTPS webhook_url and ScrapeDrive posts the result there when the job completes.
500 credits after you confirm your email. No card.
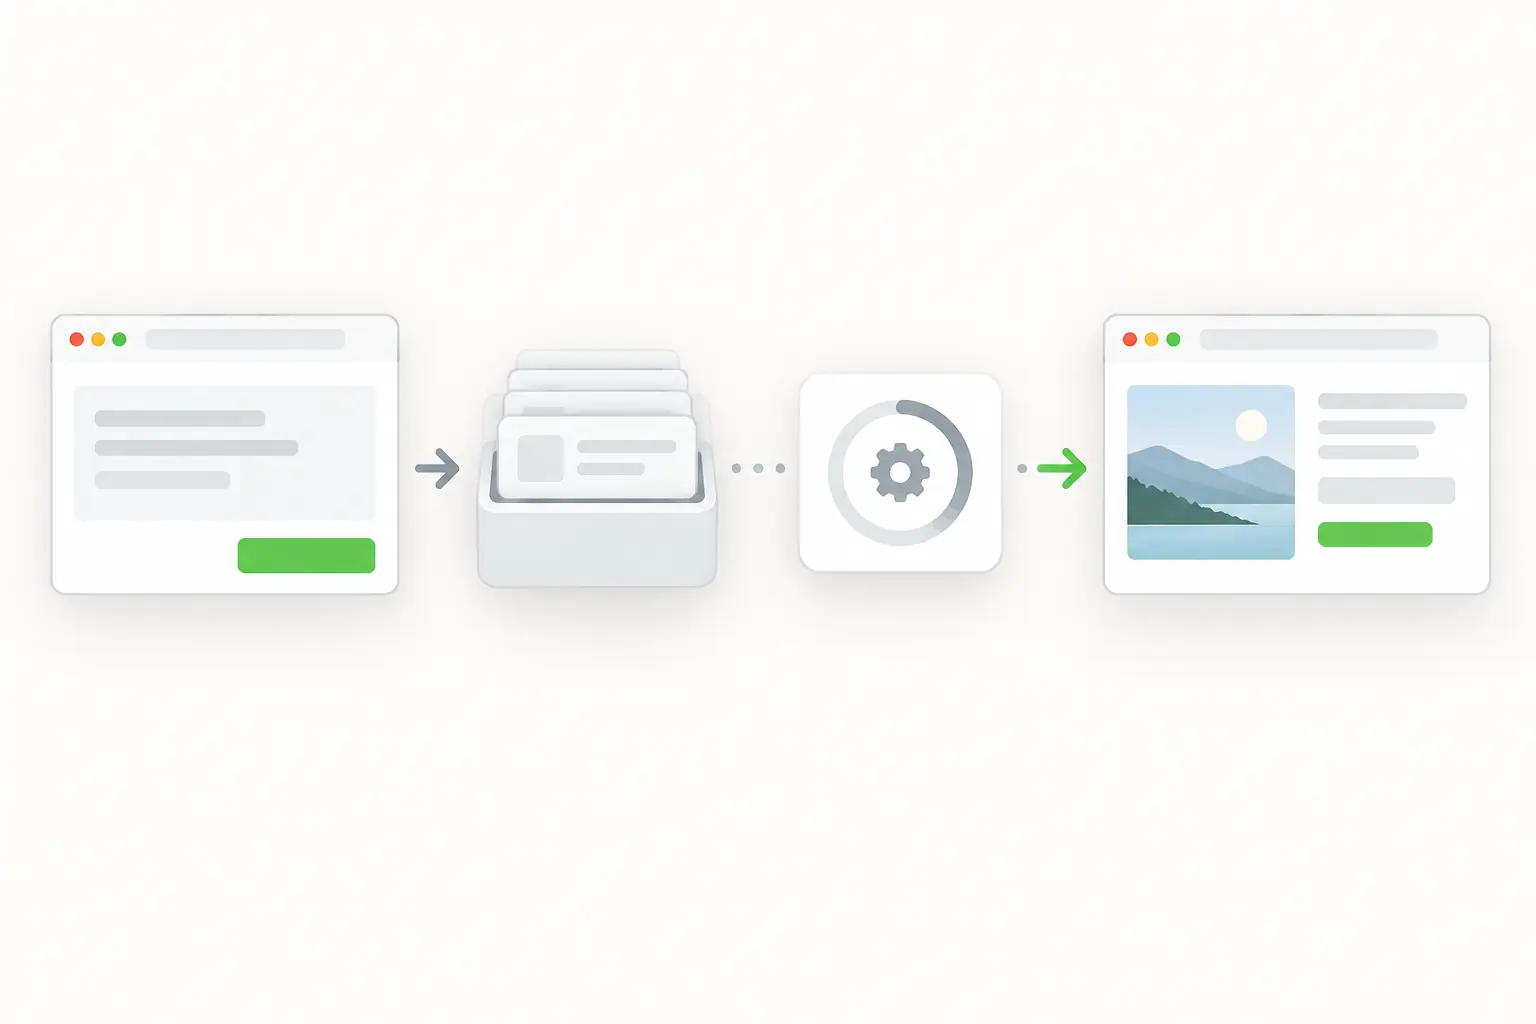
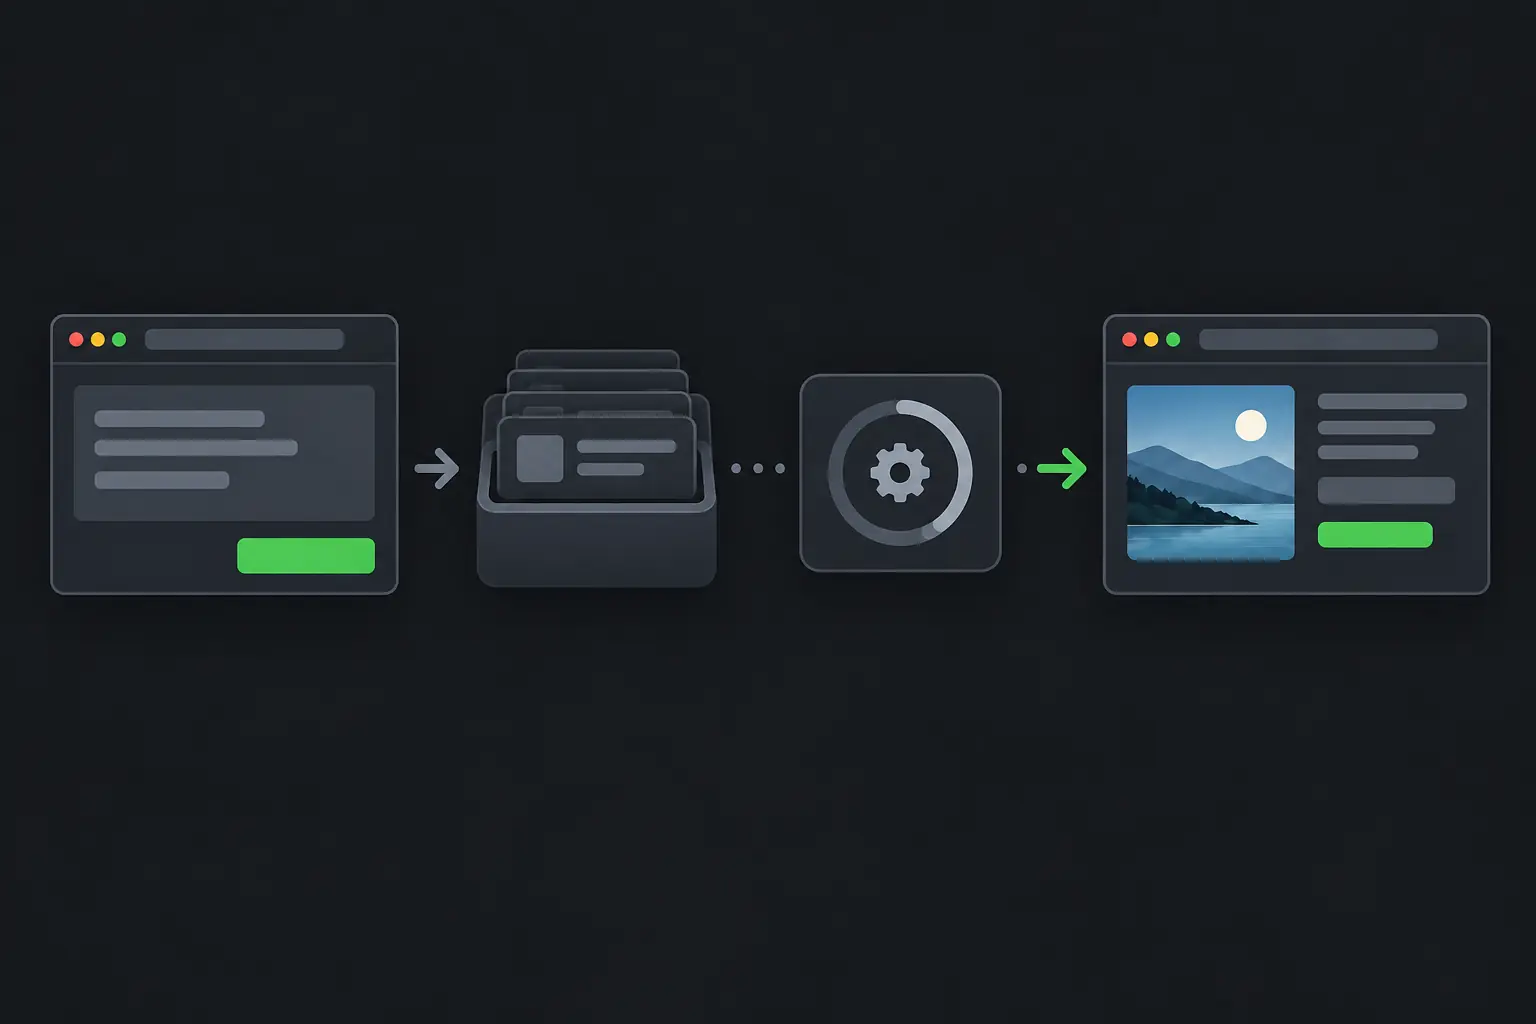
What this request asks for
- /api/v1/scrape/async
- The async endpoint. The response is the job id, its status and a status_url to poll.
- webhook_url
- Where ScrapeDrive posts the result when the job completes. Must be HTTPS.
- custom_id
- Your own reference, echoed in the webhook payload.
What it does for a request
- Returns at once
- The submission response carries the job id, its status and a status_url you can poll.
- Allows a longer job
- An async job can run for up to 130 seconds. A sync request waits up to 120.
- Delivers to a webhook
- With webhook_url set, ScrapeDrive sends a POST with the result when the job completes. custom_id, up to 255 characters, is echoed in that payload.
- Takes the same options
- Async accepts the same scrape options as sync. transparent_mode is the exception and applies to sync only.
When to use it
Use it when
- You send batches or a higher volume of requests.
- Browser jobs may need more time than a sync connection allows.
- Your system should not hold a connection open while a page loads.
Leave it out when
- A one-off request, where waiting on the connection is simpler. Sync returns the page body directly.
How to set it
Submit
GET or POST https://api.scrapedrive.com:8443/api/v1/scrape/async
With api_key.
Poll
GET https://api.scrapedrive.com:8443/api/v1/job/{id}
No api_key. The job id grants access to the result.
webhook_url
HTTPS URL
Async only. Ignored in sync mode.
custom_id
up to 255 characters
Echoed in the webhook payload.
Limits to plan for
- Treat the job id like a secret. Anyone who has it can read the result.
- Reading a finished result shortens how long it stays available. Save the whole response the first time you read it.
- A completed status means the job ended, not that it succeeded. Check response.status_code and reason before you use the body.
- Over the async backlog limit, a submission returns 429 and is not charged.
Other features
Start with a plain request. Add browser, routing or waiting settings only when the page needs them.
Automatic routing
ScrapeDrive picks HTTP or browser, proxy pool and location, under the max_credits ceiling you set.
See the feature, Automatic routingJavaScript rendering
Load the page in a real browser so content that scripts add is in the result.
See the feature, JavaScript renderingProxy routing
Send a Standard request through datacenter or residential proxies, or through your own proxy.
See the feature, Proxy routingGeo targeting
Route a residential Standard request through the country you name with proxy_country.
See the feature, Geo targetingWebpage screenshots
Add an image of the viewport, the full page or one element to a request.
See the feature, Webpage screenshotsOutput formats
Choose HTML, visible text or Markdown with result_type, at the same price.
See the feature, Output formatsBrowser waits
Hold a browser request for a load event, a CSS selector or a fixed delay.
See the feature, Browser waitsHeaders and sessions
Pass your own headers to the site and keep one proxy session across related requests.
See the feature, Headers and sessionsCost controls
Work out the price from the parameters, cap Auto with max_credits and read the settled charge.
See the feature, Cost controls
Try async requests on your page
Paste a page URL into the Playground and see exactly what ScrapeDrive returns.
500 credits after you confirm your email. No card.