Coming soon
Crawl a website
Crawl is a planned feature. It will start from one URL and fetch the pages of that website, so you will not need a list of page URLs before you begin. It is not available in the API yet.
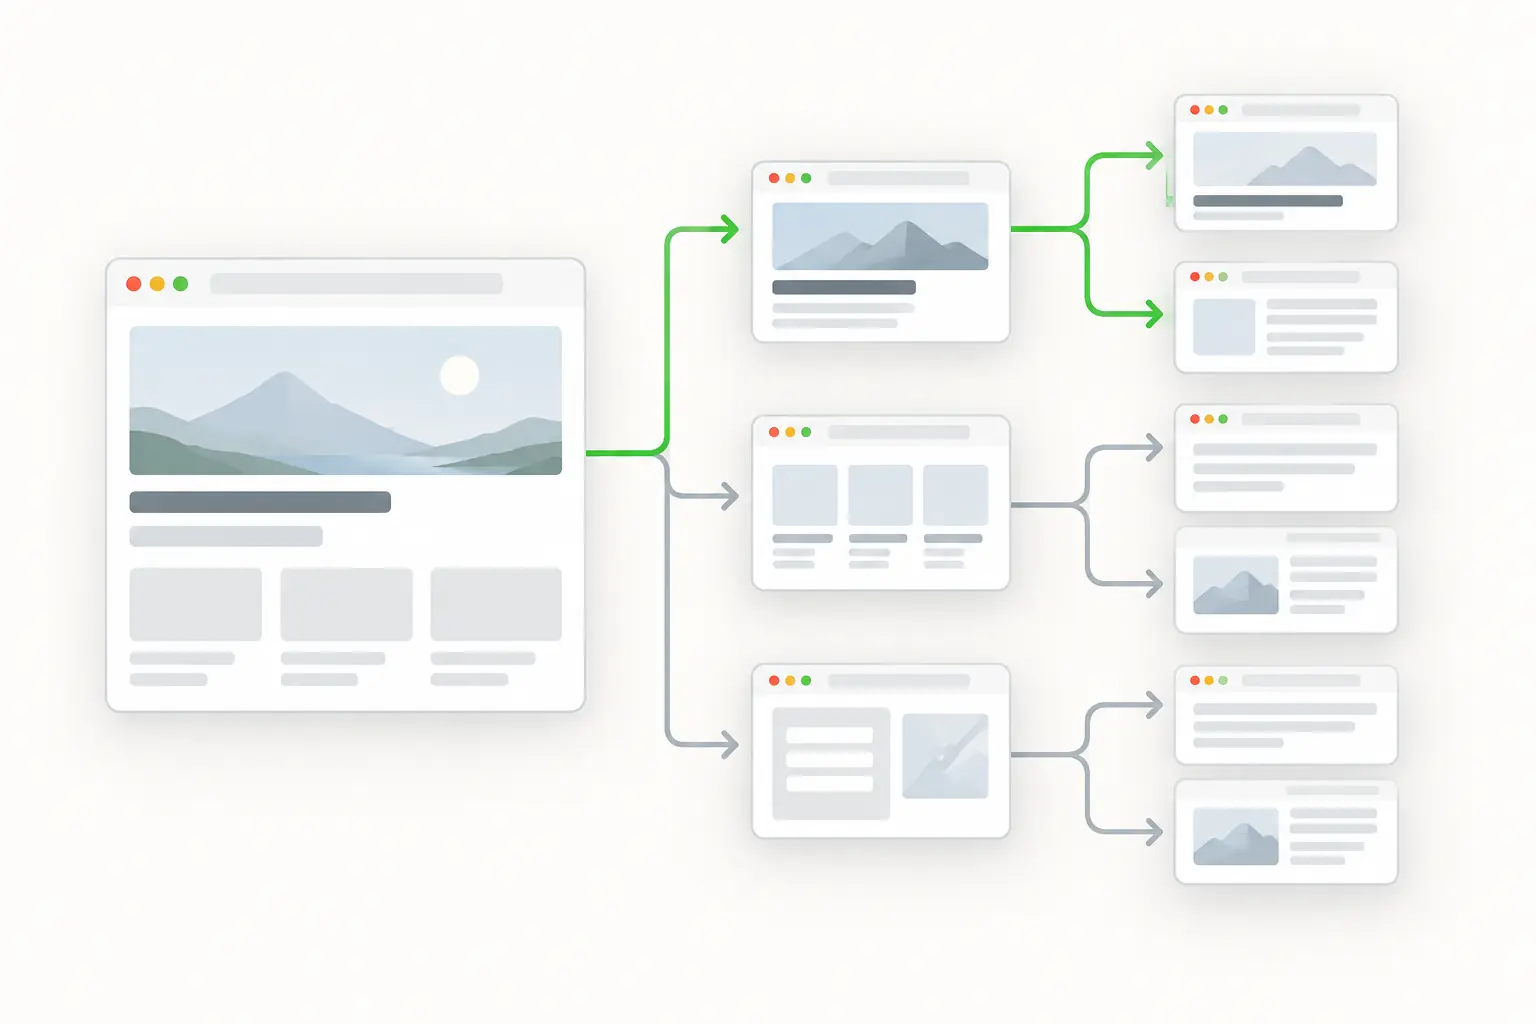
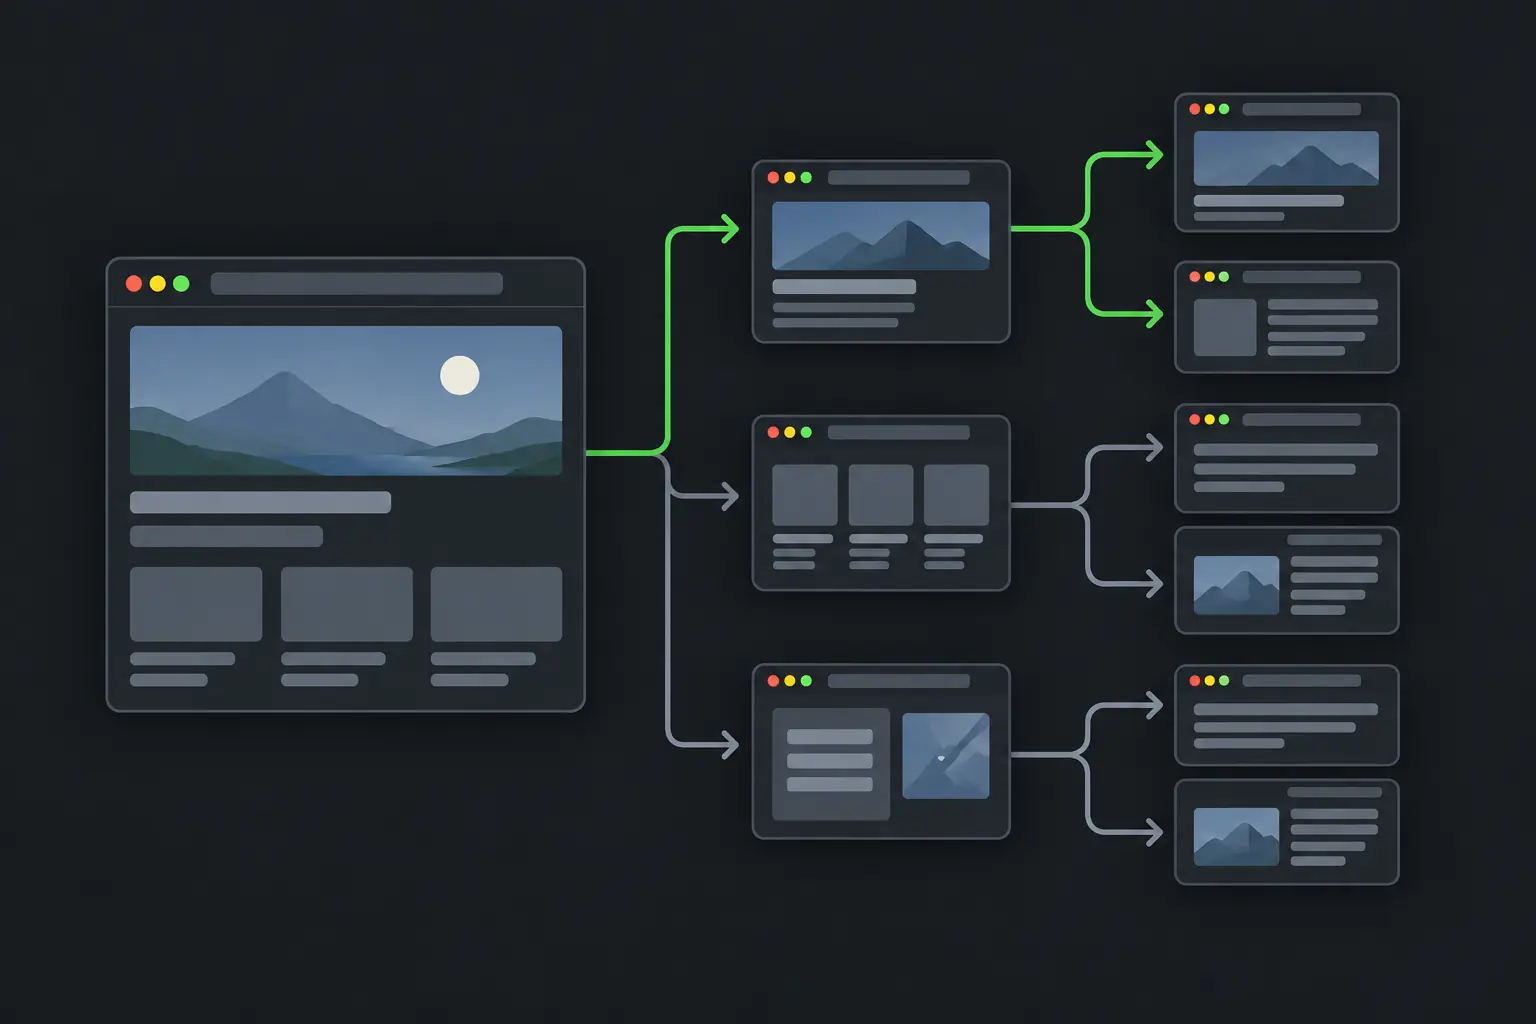
What it will do
- What you will send
- The URL the crawl will start from. Any settings for how far a crawl goes will be documented when the feature ships.
- What you will get back
- The pages of the website the crawl reaches. How results will be delivered and priced will be announced in the changelog.
Where it will help
- Collecting the product pages of a store when you do not have a list of their URLs.
- Fetching the pages of a documentation site to keep a copy of it.
- Gathering the articles of a blog or news section in one job instead of one request per page.
Why it will help
- Today every ScrapeDrive request fetches one page you already know the URL of. Finding those URLs is work you do before the first request.
- A crawl will start from the site itself, so that step moves into ScrapeDrive.
Other planned features
Planned features. None of them is available in the API yet.
Find Sitemap
Coming soonPlanned: find where a website publishes its sitemap, so you can see the site's own list of pages before you fetch any.
Read the plan, Find SitemapExtract DESIGN.md
Coming soonPlanned: analyze a reference website and produce a DESIGN.md design brief your coding agents can follow.
Read the plan, Extract DESIGN.md
Hear when Crawl ships
Released features are announced in the changelog. The features on the features page work today.