Capture the page as an image
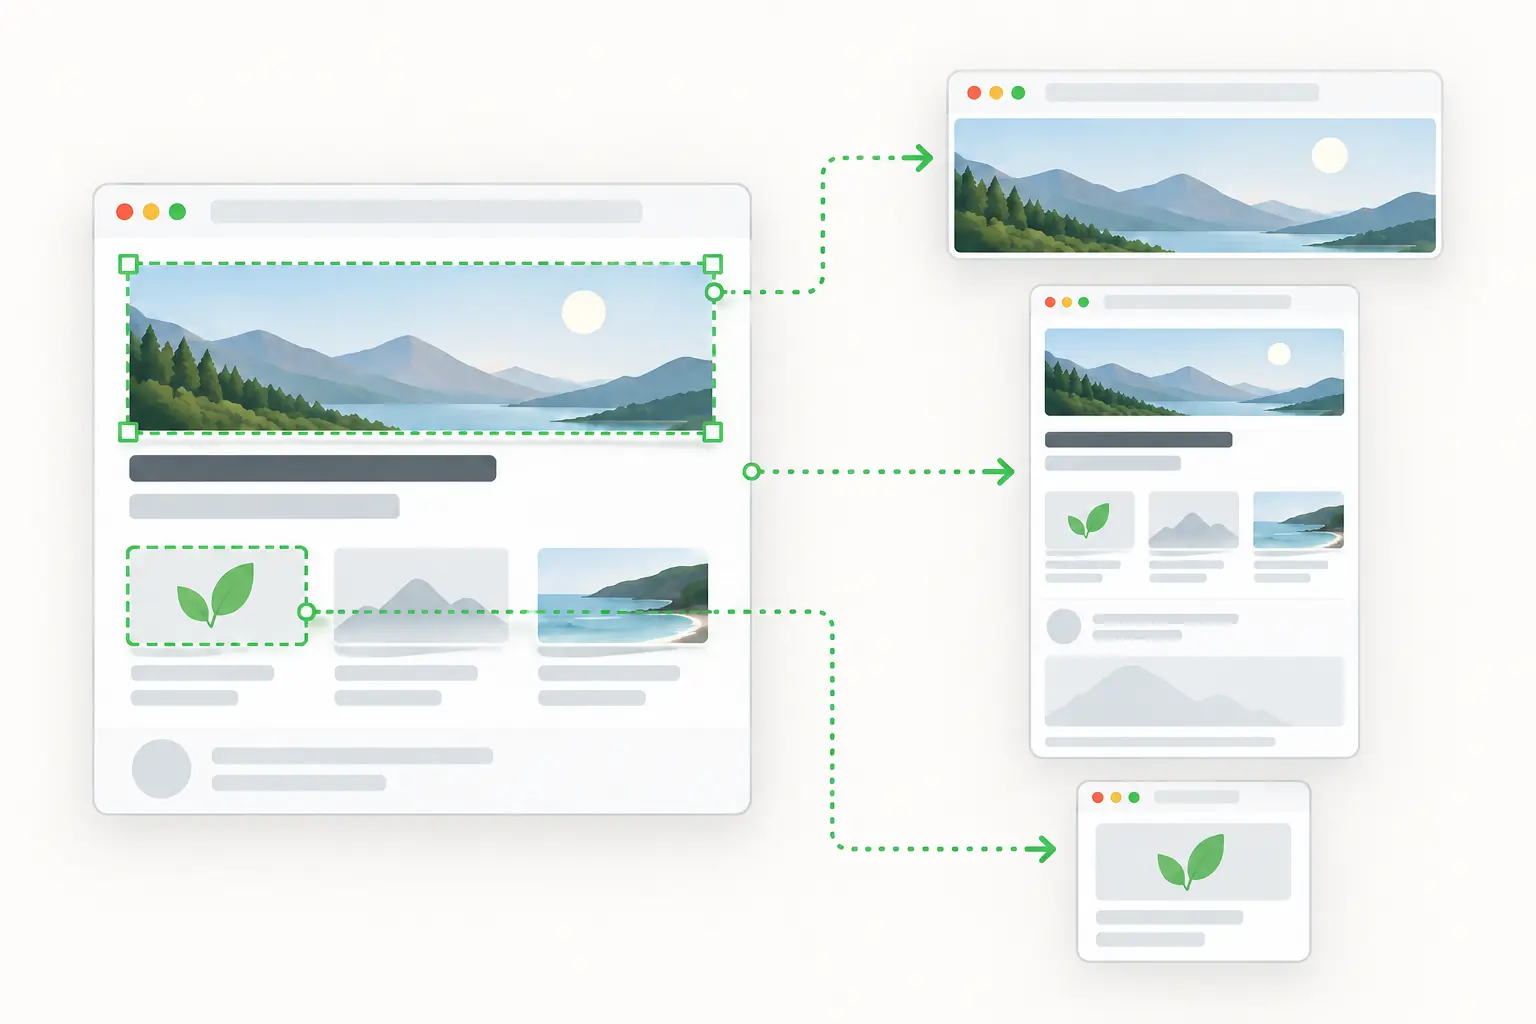
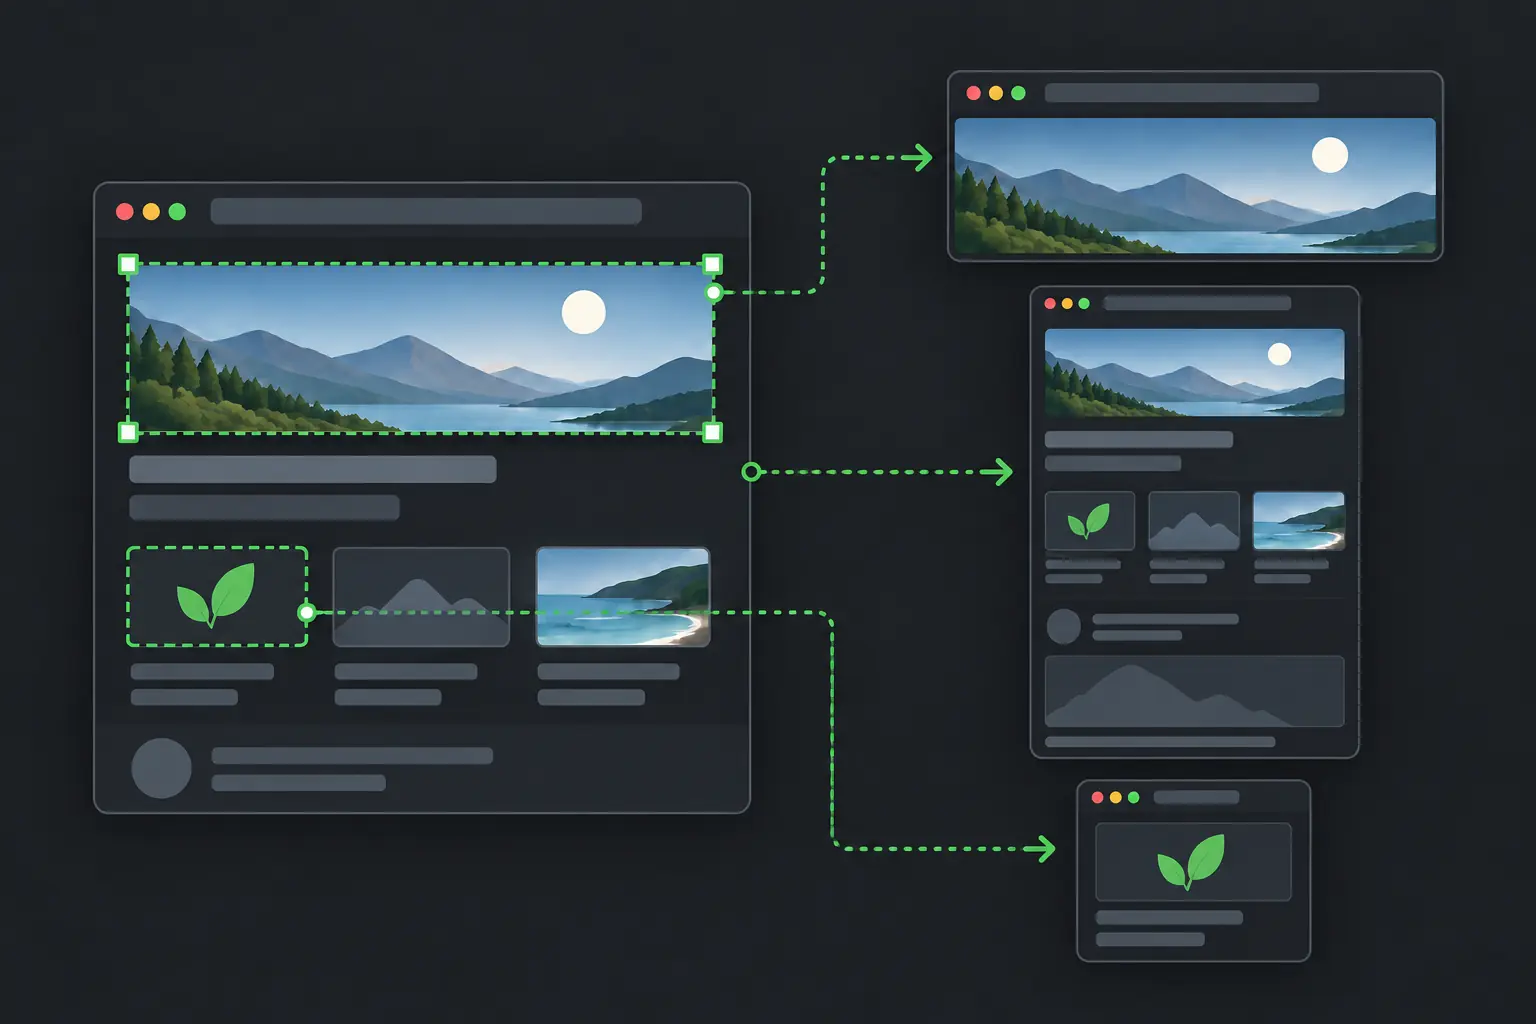
A screenshot request returns the page as usual and adds an image of it. Choose the visible viewport, the whole scrollable page, or one element picked by a CSS selector. The image URL comes back in the x-sdrive-screenshot-url response header.
500 credits after you confirm your email. No card.
What this request asks for
- screenshot_fullpage=true
- Captures the entire scrollable page. A browser is switched on for it.
- x-sdrive-screenshot-url
- The response header that carries the image URL.
What it does for a request
- Three capture modes
- screenshot=true captures the visible viewport, screenshot_fullpage=true the whole page, and screenshot_selector one element.
- Switches a browser on
- A screenshot needs a browser, so ScrapeDrive enables rendering for you.
- Loads visual resources
- block_resources is turned off so images, CSS and fonts load. block_ads stays as you set it.
- Adds 5 credits
- 15 credits on the datacenter network, 20 on residential.
- Returns the image URL
- A sync response carries it in the x-sdrive-screenshot-url header. For an async job it is in response.headers of the polled result.
When to use it
Use it when
- You want a visual record of what a page showed when you fetched it.
- You need to see a layout, not only its text. Add device_type=mobile for the mobile layout.
Leave it out when
- You only need the HTML, text or Markdown. The same request without a screenshot costs 5 credits less.
How to set it
screenshot
true or false
Captures the visible viewport.
screenshot_fullpage
true or false
Captures the entire scrollable page. Slower and larger than the viewport.
screenshot_selector
CSS selector
Captures one element. The request returns an error when the element is not found.
device_type
desktop or mobile
The emulated viewport and user agent. The default is desktop.
Limits to plan for
- A full-page capture takes longer and produces a larger image than a viewport capture.
- Download the image when the response arrives, rather than keeping only the link.
- Content that appears late can be missing from the capture. Browser waits hold the request for an element or a delay.
Other features
Start with a plain request. Add browser, routing or waiting settings only when the page needs them.
Automatic routing
ScrapeDrive picks HTTP or browser, proxy pool and location, under the max_credits ceiling you set.
See the feature, Automatic routingJavaScript rendering
Load the page in a real browser so content that scripts add is in the result.
See the feature, JavaScript renderingProxy routing
Send a Standard request through datacenter or residential proxies, or through your own proxy.
See the feature, Proxy routingGeo targeting
Route a residential Standard request through the country you name with proxy_country.
See the feature, Geo targetingOutput formats
Choose HTML, visible text or Markdown with result_type, at the same price.
See the feature, Output formatsAsync requests
Get a job id at once, then poll for the result or receive it at an HTTPS webhook.
See the feature, Async requestsBrowser waits
Hold a browser request for a load event, a CSS selector or a fixed delay.
See the feature, Browser waitsHeaders and sessions
Pass your own headers to the site and keep one proxy session across related requests.
See the feature, Headers and sessionsCost controls
Work out the price from the parameters, cap Auto with max_credits and read the settled charge.
See the feature, Cost controls
Try webpage screenshots on your page
Paste a page URL into the Playground and see exactly what ScrapeDrive returns.
500 credits after you confirm your email. No card.